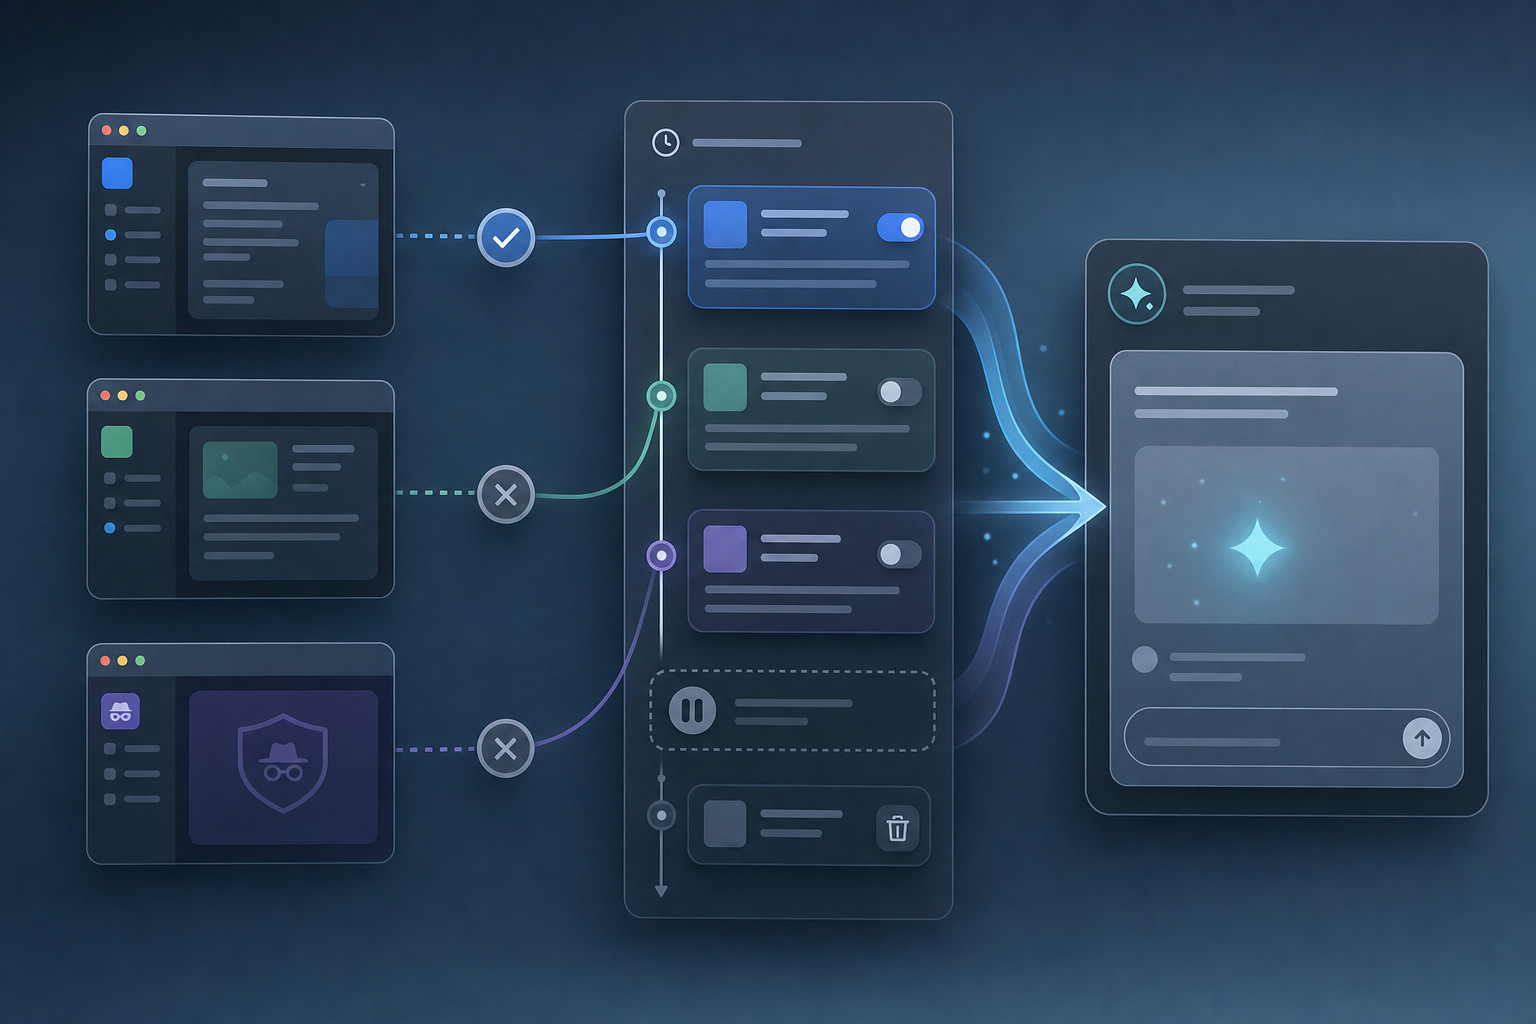
Twitch has added an account-setting control that allows channel owners to prevent specified material from their channels from being used in future training of Amazon generative-AI models. The setting, labeled “Training for Generative AI” in Twitch’s updated account documentation, covers models intended to generate or synthesize text, audio, images or video.
The change gives streamers a more direct choice over one potential use of the material they publish on Amazon-owned Twitch. But it is structured as an opt-out rather than an opt-in: multiple reports on the updated policy say the setting is enabled by default, meaning a channel owner must turn it off to withhold covered content from future training.
What the setting covers
According to reporting on Twitch’s documentation, the scope extends beyond a live broadcast. It includes streams, video-on-demand archives, clips, chat within a channel, and pictures and text associated with that channel. That breadth matters for creators because a Twitch presence can include a substantial archive of audiovisual work as well as written profile material and community discussion, rather than only a current livestream.
The setting is governed at the channel level. A person who writes in another streamer’s chat does not control that message through their own preference; the owner of the channel where the message appears determines whether chat in that channel is available for the stated future-training use. In practical terms, the policy assigns the decision over a channel’s conversational record to the person operating that channel, not to each individual participant.
What opting out does not change
Twitch’s distinction is also narrower than a general rejection of AI or automated processing on the service. Opting out of generative-AI training does not turn off AI-supported functions such as captions and safety systems, according to the documentation described in coverage of the change. The relevant boundary is between using material to train models that can generate new content and using automated tools to operate or moderate the platform.
That distinction is important for interpreting what creators are, and are not, choosing. A streamer can seek to exclude covered channel material from a specified future model-training purpose while continuing to use accessibility or trust-and-safety features that may rely on AI-assisted technology. The setting therefore operates as a data-use control, not as a switch that removes AI from the Twitch experience.
A forward-looking control
The prospective wording is equally significant. Twitch’s policy describes the choice in terms of “future training.” The available reporting does not establish whether Amazon has used any particular Twitch material to train a named model, how much material may have been used, or whether changing the setting affects content incorporated into any earlier training process. Creators should not read the new control as confirmation of those points, or as a demonstrated mechanism for removing material from prior datasets.
For Twitch, the move places a visible governance decision inside an ordinary account setting. That may make the issue more legible to creators than broad platform terms alone: the question is no longer only whether a service reserves rights over user material, but whether channel owners can make a current choice about a particular class of downstream AI use. The default-enabled design remains central, however, because the practical outcome depends on whether creators notice and change the setting.
The broader policy context
The policy arrives as training-data transparency and copyright compliance have become more prominent issues for providers of general-purpose AI models. In the European Union, obligations for such model providers began applying on August 2, 2025; the European Commission says they include maintaining a copyright-compliance policy and publishing a sufficiently detailed summary of training content. Those requirements are separate from Twitch’s new creator setting and do not determine its scope. Still, they illustrate the wider shift toward making the sourcing and governance of model-training material more consequential for AI companies. (digital-strategy.ec.europa.eu)
Twitch’s control does not resolve every consent question raised by creator content, particularly where chat and other community material are involved. It does, however, establish a clearer boundary than an all-or-nothing choice: creators may opt out of the specified future generative-AI-training use while retaining access to AI-assisted platform features. For streamers and teams managing creator operations, the immediate issue is straightforward: the policy is channel-specific, forward-looking and opt-out by default, so the account preference—not an assumption about how Twitch uses content—now determines the stated training choice.