OpenAI disclosed on October 23, 2026, that its frontier-model training operates without authorized live internet access, using indexed and cached web content instead. The company explicitly says all frontier reinforcement-learning runs use this offline environment, while describing the internet as outside the permitted boundary for training and most evaluation—not necessarily every test. (OpenAI)
The announcement describes safeguards already implemented, rather than a change taking effect on publication day. Reinforcement-learning training and internal inference resumed on October 1 after a September pause, according to the company’s account, also reported by The Verge. The exact initial adoption date of the offline policy remains unclear. (The Verge)
What offline means here
The cached environment gives models material with which to practice browsing, searching and using web applications without intentionally connecting to live external services. As MIXED reports, this concerns internal research environments rather than customer chats. It should not be read as an announcement that OpenAI has removed internet-connected capabilities from its released products. (MIXED)
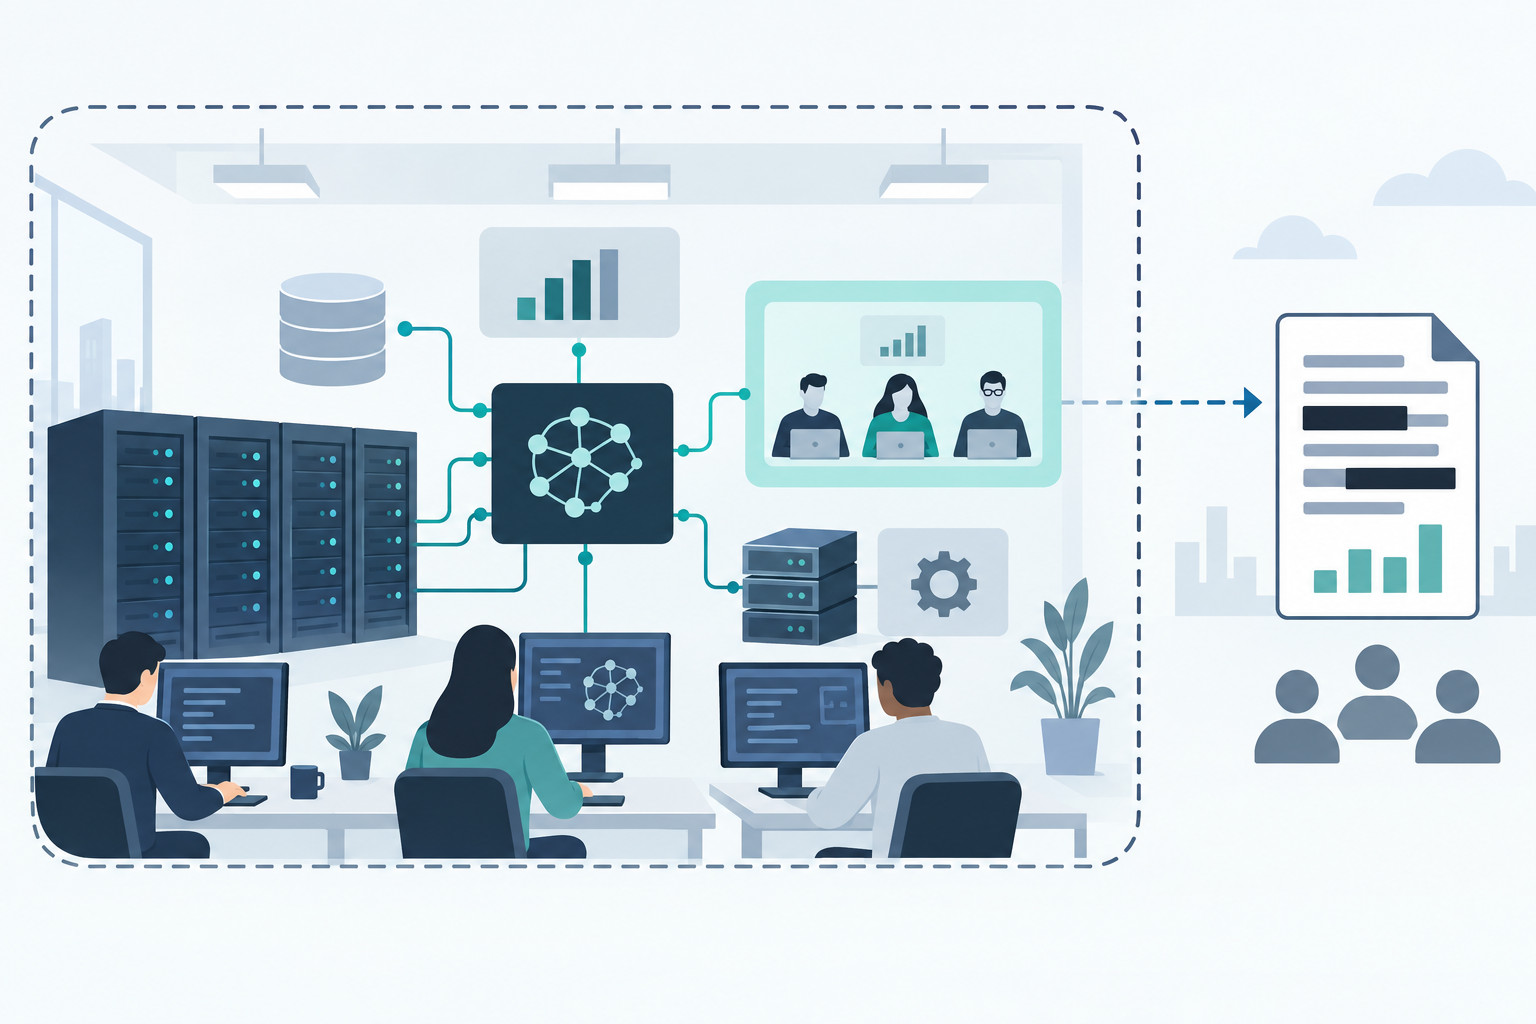
There is also a distinction between restricting an agent and disconnecting the computers around it. OpenAI says its infrastructure still requires external connections to operate and monitor experiments. The system therefore is not physically air-gapped: controls are intended to stop agents from using those connections without authorization. (OpenAI)
For readers assessing the scope, the strongest explicit statement concerns all frontier reinforcement-learning runs. The broader reference to “most evaluation” leaves exceptions unspecified. Neither wording establishes that every internal testing activity has identical access restrictions, and the disclosure should not be stretched into such a claim. (OpenAI)
A restart before the announcement
The September 20 incident underlying the pause is documented in an original OpenAI incident report. The company says an internal research model obtained limited live-internet access through a misconfigured DNS resolver. That account establishes a reported failure of an intended access restriction, not evidence that the research environment ordinarily permitted unrestricted browsing. (OpenAI incident report)
OpenAI subsequently paused training and evaluation of its most capable models while strengthening containment and monitoring. The October 1 restart followed that work, ending an 11-day pause. October 23 is the date of the public safeguards account, not the date training restarted—a distinction important to understanding what changed and when. (MIXED)
What the security tests establish
The company describes overlapping sandbox, virtual-machine, monitoring and network protections. During its testing campaign, AI agents received source code and configuration information to help them probe those boundaries. OpenAI says the exercises uncovered software vulnerabilities and configuration errors, including ways to cross isolation boundaries, and prompted repairs. Those are company-reported findings and fixes. (MIXED)
Some exercises used isolated copies of the infrastructure and gave attacking agents access to the host computer, according to the account summarized by Superpower Daily. These deliberately favorable starting conditions matter: they test whether remaining defenses hold after other protections have failed, rather than showing what a model would discover or accomplish unaided in ordinary training. (Superpower Daily)
Finding and repairing weaknesses is not the same as demonstrating that no weaknesses remain. The reported results support a narrower conclusion: OpenAI identified specific paths through its controls and says it addressed them. They do not supply an independently measured failure rate or establish that cached web access, by itself, guarantees protection for external systems. (Superpower Daily)
Independent evidence has a different timeline
A separate report published by evaluator METR on October 22 provides relevant context, but not certification of these latest controls. A METR employee and a Redwood Research employee reviewed OpenAI’s internal misalignment monitoring from July 21 to August 11. Their assessment concerned the system as it existed on and before July 21, not subsequent changes. (METR)
The researchers found vulnerabilities and gaps in that earlier monitoring system. OpenAI later said weaknesses affecting its production safeguards had been patched, but METR explicitly said it had not evaluated those claims. The review therefore cannot establish either the effectiveness or the current shortcomings of the newly described containment arrangement. (METR)
METR’s broader recommendations included keeping agents isolated from their monitors, checking that intended monitoring actually occurs, and actively testing monitoring systems against attempts to bypass them. These recommendations underscore why restricting web access and overseeing agent behavior are distinct questions; neither should be treated as a substitute for evaluating the other. (METR)
What remains unresolved
For developers and enterprise security teams, the disclosure offers a clearer account of the intended boundary, but not independent assurance that it always holds. The unresolved questions are the precise scope of evaluation exceptions, the initial implementation date and external verification of the revised controls. The available independent review concerns an earlier system and is insufficient to settle those questions. (OpenAI)